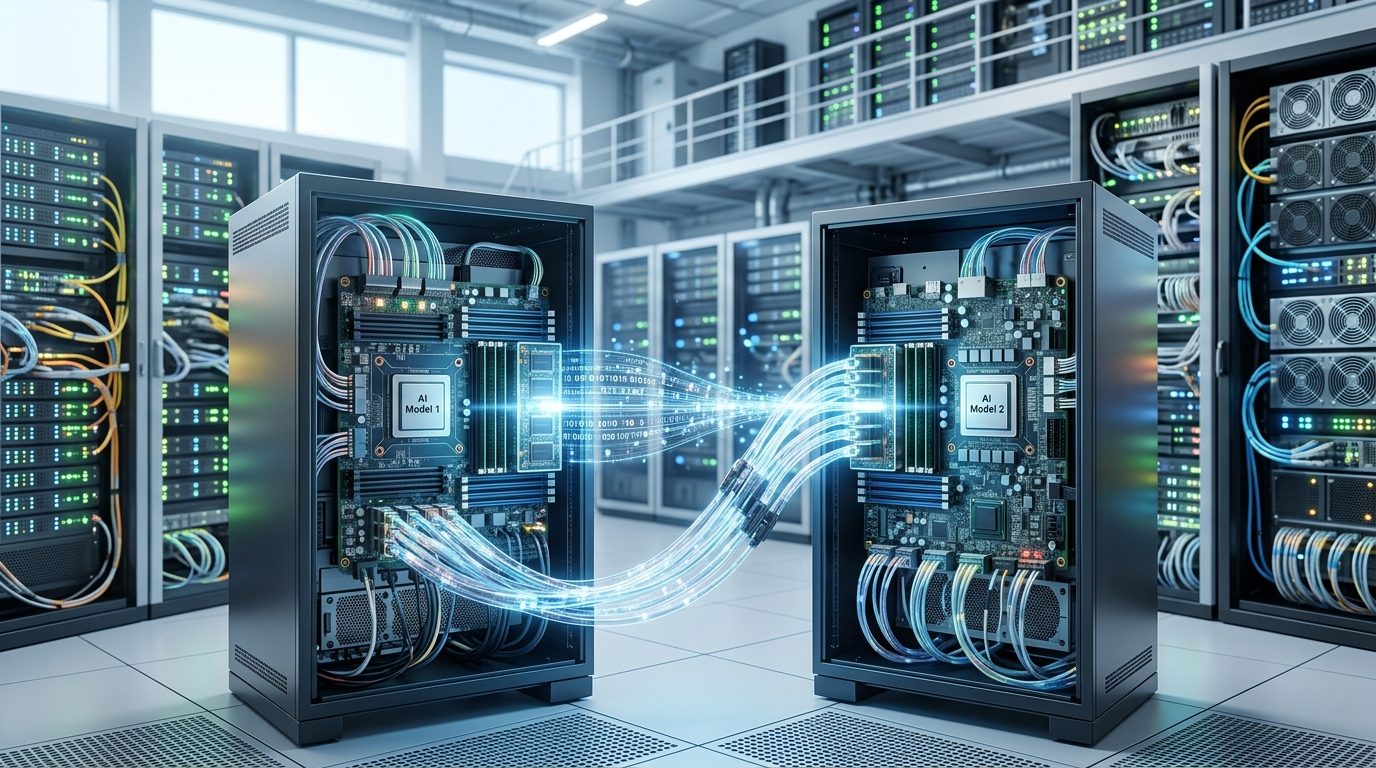
C2C offers a new way for artificial intelligence models to communicate, replacing text exchanges with direct access to key-value caches. The method is designed to improve benchmark accuracy and cut response times for teams that manage their own inference systems.
The approach targets a common source of waste in multi-model AI systems. One model often turns its work into text before another model reads and processes that text again. C2C seeks to avoid those repeated steps by passing internal model context through KV caches.
How Cache-Based Communication Works
AI models process input as tokens, which are small units of text. During inference, transformer models store intermediate information in a key-value cache, often called a KV cache. This prevents the model from recalculating earlier tokens whenever it produces a new answer.
C2C uses that stored information as a communication channel between models. Instead of generating a written message for the next model, a system can transfer relevant cached states directly.
“C2C lets AI models communicate through KV caches instead of text, improving benchmark accuracy and reducing latency.”
The claimed accuracy gain may come from preserving information that would otherwise be compressed into words. Text can omit detail, add ambiguity, or force one model’s internal reasoning into a format that another model must interpret.
Lower latency could result from reducing text generation and repeated prompt processing. Those operations can become costly when several models or agents work in sequence.
Benefits Depend on Infrastructure Control
The technique is most relevant to organizations that control their inference stack. These teams can manage model execution, memory, cache formats, routing, and hardware placement.
Potential gains may include:
- Fewer tokens generated solely for communication between models.
- Less repeated processing of shared context.
- Faster handoffs in multi-model workflows.
- More detailed information transfer than text may permit.
That requirement also limits immediate adoption. Many companies access models through hosted application programming interfaces. Such services usually return text or structured output, but do not expose internal KV caches.
Compatibility is another concern. Models can differ in architecture, tokenization, layer count, hidden-state size, and cache layout. A cache produced by one model may not be usable by another without an adapter or shared design.
Accuracy Claims Need Wider Testing
Benchmark improvements offer an early sign of value, but they do not establish performance across production workloads. Results can vary by model pairing, task type, prompt length, hardware, and evaluation method.
Direct cache exchange may also create security and privacy questions. Internal states could retain sensitive details from prompts or earlier processing. Operators would need controls for access, retention, isolation, and deletion.
Debugging could become harder as well. Text messages are easy for developers to inspect. KV caches are machine-oriented representations, making failures less transparent to human reviewers.
A New Trade-Off for AI Teams
C2C reflects a wider shift from single-model chat tools to systems where several models divide tasks. As those systems grow, communication overhead can affect speed, cost, and output quality.
Text will remain useful where auditability and compatibility matter most. Cache-based communication may fit controlled deployments that place greater weight on performance and retain access to the full inference pipeline.
The next test will be whether C2C delivers consistent gains across different models and real applications. Independent benchmarks, compatibility studies, and security reviews will help determine whether KV-cache communication can move from a specialized optimization to a practical design choice.
Rashan is a seasoned technology journalist and visionary leader serving as the Editor-in-Chief of DevX.com, a leading online publication focused on software development, programming languages, and emerging technologies. With his deep expertise in the tech industry and her passion for empowering developers, Rashan has transformed DevX.com into a vibrant hub of knowledge and innovation. Reach out to Rashan at [email protected]